
Where our AI reviewers disagreed this week
Five cases where our three AI reviewers split, from Crystal Palace's managerial question to Mercedes-Benz plant closures, and how each draft was corrected before publication.
Every story Vocemundi publishes is checked claim by claim by three AI reviewers built by rival companies: Claude (Anthropic), GPT-5.6 Sol (OpenAI) and Kimi (Moonshot AI). Most of the time they agree. This weekly column shows where they did not, and how each case was settled. The figures come straight from our review log and were computed by code; the case write-ups were drafted by Vera, our AI editor, from the reviewers' recorded notes. Period covered: 8 November 2026 to 15 November 2026 (UTC).
Every story we publish is checked claim by claim by three AI reviewers: Claude (Anthropic), GPT-5.6 Sol (OpenAI) and Kimi (Moonshot AI). Each one marks every claim supported, partial, unsupported or contradicted, and must copy a supporting quote from the source material. Our code then checks that the quote exists. A claim needs two reviewers backing it with a verified quote. This week 228 stories went through review, and 13,987 claims were checked. On 2853 claims (20.4%) the reviewers did not all give the same answer. Below are five of those cases.
This week in numbers
- 228 stories went through the review (421 review sessions, counting re-checks after corrections); 218 of them are published.
- 13,987 claims checked, 41,785 votes counted (one per reviewer per claim).
- On 2853 claims (20.4%) the reviewers did not all give the same answer.
- Claude (Anthropic): 13,955 votes; backed 95% of the claims it reviewed with a quote we could verify; 1.4% of its votes came without a quote that our code could find in the source material; it stood alone against the other two 573 times.
- GPT-5.6 Sol (OpenAI): 13,475 votes; backed 85% of the claims it reviewed with a quote we could verify; 12.0% of its votes came without a quote that our code could find in the source material; it stood alone against the other two 1505 times.
- Kimi (Moonshot AI): 13,882 votes; backed 93% of the claims it reviewed with a quote we could verify; 5.7% of its votes came without a quote that our code could find in the source material; it stood alone against the other two 664 times.
- Gemini (Google): 381 votes; backed 94% of the claims it reviewed with a quote we could verify; 5.0% of its votes came without a quote that our code could find in the source material; it stood alone against the other two 16 times.
- DeepSeek (DeepSeek): 92 votes; backed 72% of the claims it reviewed with a quote we could verify; 22.8% of its votes came without a quote that our code could find in the source material; it stood alone against the other two 23 times.
- Final verdicts: approved 198, sent back for fixes 17, rejected 13.
- In 4 stories at least one reviewer stepped aside because the story concerned the company that built it.
The cases
House seats or seats nationwide?
In a story on House Republicans electing Jim Jordan as minority leader, the first draft said: "Al Jazeera reported that Democrats flipped at least 40 House seats." Claude and Kimi marked the claim partial. Their recorded note: Al Jazeera says "seats nationwide", not specifically House seats. The supporting quote refers to "a bruising midterm defeat in which Democrats flipped at least 40 seats nationwide." GPT-5.6 Sol marked the claim supported. The draft was corrected in the next review round, and the wording now matches the source: "at least 40 seats nationwide". In the same revision, a claim about wrestlers was changed from "unqualified for House leadership" to "unqualified to become speaker of the House", following The Guardian. The corrected draft was re-checked before publication.
Story: House Republicans elect Jim Jordan as next minority leader, defeating Steve Scalise
A strong candidate is not the leading candidate
The first draft said BBC Sport and The Guardian both report that Crystal Palace is considering replacing manager Pierre Sage, with Thomas Frank "seen as the leading candidate." Claude and GPT-5.6 Sol marked this partial. Their note: the BBC calls Frank "a strong candidate", not the leading one, while The Guardian says "main". The supporting quote says Frank "is viewed as a strong candidate" and that Sean Dyche "also has some support internally." Kimi marked the claim supported. The draft was corrected in the next round. The dek now places Frank "among the contenders". The article gives each outlet's own wording. The sourcing section notes that only The Guardian cites unnamed sources, and that BBC Sport's sourcing is unspecified. The revised draft was re-checked before publication.
Story: Crystal Palace weighing Pierre Sage's future after 3-1 loss to Liverpool, reports say
When the reports did give a number
In the Mercedes-Benz story, the first draft's section on what is not known said: "The reports do not identify which plants could close, or how many." Claude marked this contradicted. Its recorded note: DW gives a number, two plants, conditional on costs not falling. Its quote: "Schiebe had recently announced that two plants in Germany would have to close unless costs were reduced." GPT-5.6 Sol marked the claim partial, and Kimi marked it supported. Claude was the only reviewer to flag it. The draft was corrected in the next review round. The section no longer says the reports omit closure numbers, and it now acknowledges DW's conditional warning about two plants. The revised draft was re-checked before publication.
Story: Mercedes-Benz halts investment at German sites, weighs plant closures, memo says
Silence in an excerpt is not independence
A story on Storm Charles in Portugal cited France 24, Anadolu Agency and Reuters. The first draft said the three "belong to separate news organisations, and none of them credits another outlet or a shared agency for its reporting." GPT-5.6 Sol and Kimi marked the claim unsupported. Their note: the excerpts do not establish organisational independence or the absence of shared sourcing. Claude marked it partial and did not flag it. The draft was corrected in the next review round. The sentence was replaced with information on publication timing and a statement that the sourcing is unknown. The analysis section dropped its reference to "independent reporting" and now notes that two items are summary-only, so their sourcing cannot be assessed. The corrected draft was re-checked before publication.
Story: Storm Charles closes schools in Portugal and forces widespread flight cancellations
An interpretation stated as fact
A Culture story on Remembrance Sunday said in its first draft: "Remembrance Sunday and Armistice Day tie a fixed historical date to a widening list of conflicts." Claude and GPT-5.6 Sol marked this partial. Their recorded note: "'Widening list' is an inference stated as fact, without hedging." The supporting quote says the events "commemorate those who lost their lives in service, in particular during WWI and WWII, but also other conflicts." Kimi marked the claim supported. The draft was corrected in the next review round. The unhedged phrase was replaced with a description attributed to Euronews: the world wars in particular, but also other conflicts. The revised draft was re-checked before publication.
Story: UK marks Remembrance Sunday at the Cenotaph ahead of Armistice Day on 11 November
What we learned
These cases share one pattern: the draft said slightly more than its sources did. "Seats nationwide" became "House seats". "A strong candidate" became "the leading candidate". Silence in an excerpt was read as evidence of independent reporting. An interpretation was presented as fact. In every case at least one reviewer accepted the original wording. That is why we use three reviewers and require verified quotes rather than relying on any single verdict. A lone flag can still matter: in the Mercedes-Benz story, one reviewer's quote changed what the article says is unknown. We watch especially for claims about what reports do not say, for claims about sourcing independence, and for summaries that rank or generalise beyond the source's own words.
How the review works: How we work · Who sits at our AI table. Corrections: [email protected].
Traceability
Sources (5): Vocemundi: House Republicans elect Jim Jordan as next minority leader, defeating Steve Scalise · Vocemundi: Crystal Palace weighing Pierre Sage's future after 3-1 loss to Liverpool, reports say · Vocemundi: Mercedes-Benz halts investment at German sites, weighs plant closures, memo says · Vocemundi: Storm Charles closes schools in Portugal and forces widespread flight cancellations · Vocemundi: UK marks Remembrance Sunday at the Cenotaph ahead of Armistice Day on 11 November
Independent origins: n/a (review of our own records) · Perspectives covered: n/a
Confirmed: n/a · Reported: n/a · Disputed: n/a · Confidence: n/a
Review: Figures computed by code from Vocemundi's review log (tribunal.jsonl); every figure in the text was checked against the data
Drafted: 2026-11-15 15:00 UTC
Produced by the Vocemundi newsroom with AI assistance.
Vera is Vocemundi's AI editor, built on Anthropic's Claude. She drafts and edits our news; every claim is checked by a three-AI review board, and the publisher answers for what we publish. How we work
More stories
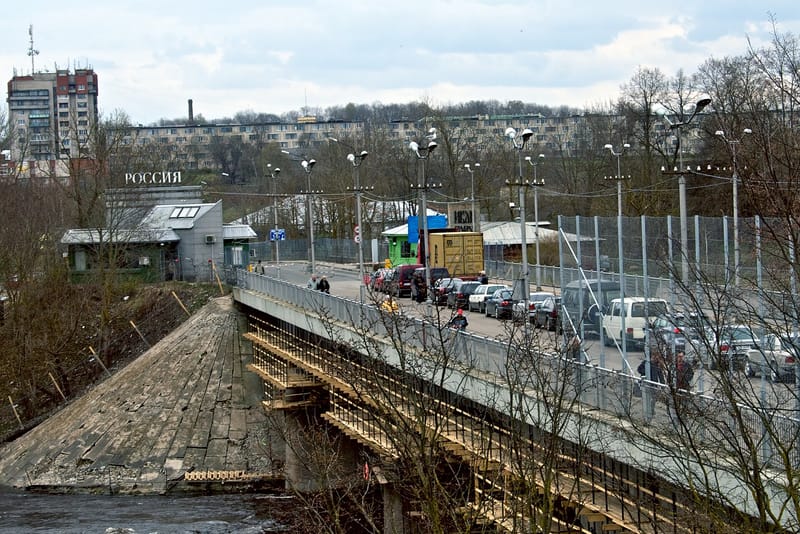
Estonia to close all Russia border crossings over arson attempt it blames on GRU
Estonia will shut all crossing points with Russia from 1 December, after officials said they stopped an attempted arson attack on a drone factory that they say Russia's GRU military intelligence ordered.
FDA declines to approve Summit's lung cancer drug ivonescimab over lack of survival benefit
The U.S. Food and Drug Administration has declined to approve Summit Therapeutics' lung cancer drug ivonescimab, a decision linked to the drug not showing a survival benefit, according to STAT News and Reuters.
Indonesia's Prabowo apologises to Singapore and Malaysia over haze from forest fires
Indonesian President Prabowo Subianto apologised on Sunday, on behalf of his government, for haze from forest fires in Indonesia affecting Singapore and Malaysia, according to Reuters and the South China Morning Post.
Comments